
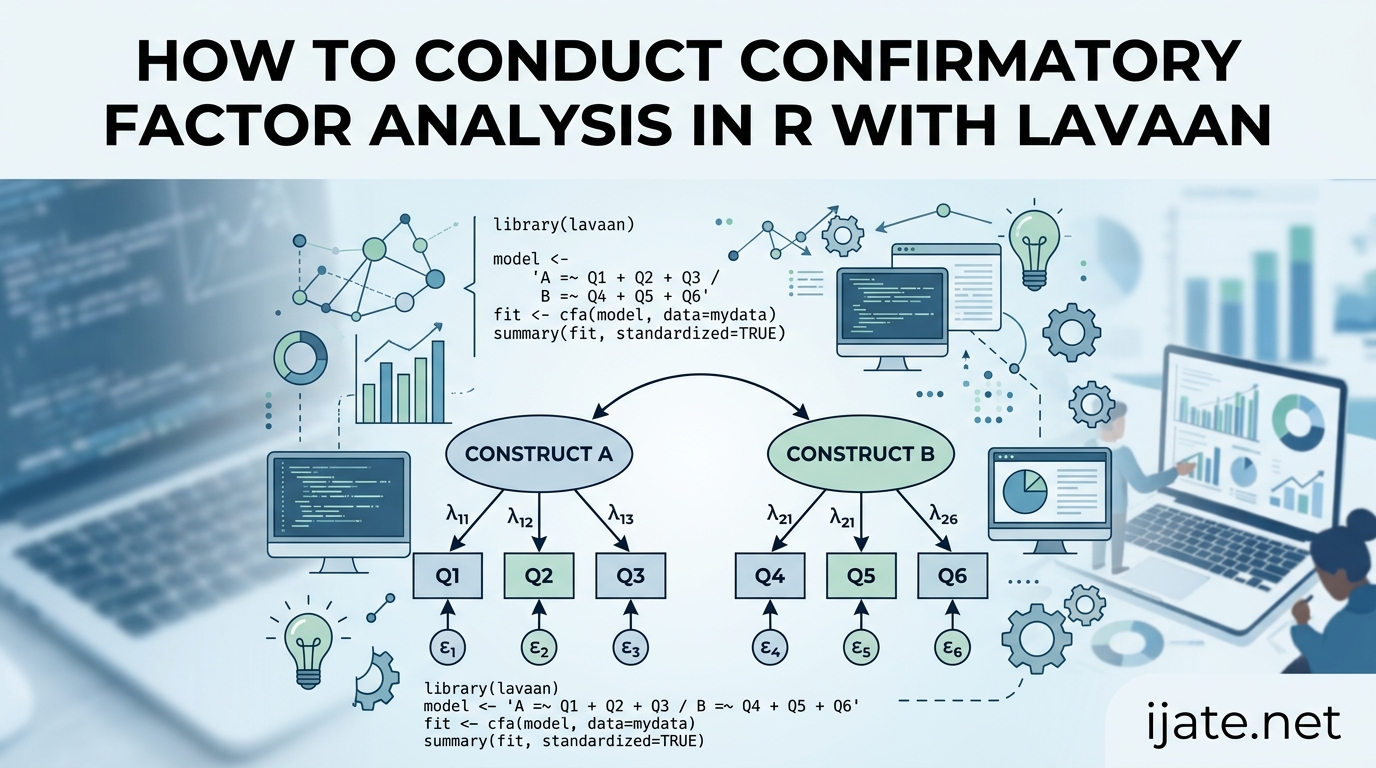
Confirmatory factor analysis (CFA) is one of the most widely used statistical techniques for validating measurement models in psychology, education, marketing, and the social sciences. If you have ever built a survey or a scale and wondered whether the items actually measure the underlying constructs you intended, CFA is the method that answers that question. In this guide, I walk through exactly how to conduct confirmatory factor analysis in R with lavaan, step by step, using real code you can run today.
The lavaan package has become the standard tool for CFA in R because it offers a clean, readable syntax for specifying models and produces output that is straightforward to interpret. Whether you are validating a new psychometric instrument or testing a theoretical factor structure from research demonstrating CFA application in published studies, the workflow I describe here covers every stage from installation through model evaluation. By the end of this tutorial, you will be able to load data, write model syntax, fit a CFA, interpret factor loadings, and evaluate model fit indices with confidence.
This article is written for researchers and analysts who already have basic R knowledge but are new to lavaan or structural equation modeling. I focus on the practical decisions you need to make at each step, the common errors that trip people up, and the thresholds that separate an acceptable model from one that needs re-specification. Everything here reflects the current version of lavaan and applies to projects in 2026 and beyond.
Table of Contents
What Is Confirmatory Factor Analysis (CFA)?
Confirmatory factor analysis is a statistical technique used to test whether a hypothesized factor structure fits observed data. You start with a theory about which observed variables (also called indicators or items) load onto which latent variables (also called factors or constructs), and CFA tells you how well that theory holds up against real data.
A latent variable is an unobserved construct that cannot be measured directly. Intelligence, anxiety, customer satisfaction, and teaching effectiveness are all examples of latent variables. We measure them indirectly through indicator variables such as test scores, questionnaire responses, or rating items. CFA formally tests whether those indicators actually reflect the latent constructs they are supposed to represent.
The key word is “confirmatory.” Unlike exploratory factor analysis, where you let the data suggest a structure, CFA requires you to specify the model in advance. You define which indicators load onto which factors, which factors are correlated, and which indicators have cross-loadings (usually none). The analysis then estimates the parameters and tells you whether the model fits.
Researchers use CFA for construct validation, psychometric testing, and scale development. Before running a full structural equation model or path analysis, you should confirm that your measurement model is sound. This is why CFA is often described as the measurement portion of SEM. If your measurement model is weak, every downstream analysis built on it will be unreliable.
CFA vs EFA: What Is the Difference?
The difference between confirmatory factor analysis (CFA) and exploratory factor analysis (EFA) comes down to how much structure you impose before running the analysis. In EFA, you let every indicator load onto every factor and the method determines the best factor structure. In CFA, you specify exactly which indicators load onto which factors based on theory.
EFA is appropriate when you are in the early stages of scale development and you do not yet know how many factors exist or which items belong to which factors. You might run EFA on a brand-new questionnaire to discover its underlying dimensions. Once you have a hypothesized structure, you confirm it with CFA on a separate sample.
This two-step process is standard practice in psychometrics. Many published studies follow this exact approach. For a combined EFA and CFA methodology example, you can see how researchers develop a scale by exploring first, then confirming.
Another key distinction is that EFA allows all indicators to cross-load on all factors, while CFA typically sets cross-loadings to zero. This makes CFA more restrictive but also more theory-driven. If your CFA model fits well, you have strong evidence that your theoretical measurement model is valid.
One question that comes up frequently on forums is whether to choose CFA or path analysis. Path analysis examines relationships between observed variables without latent variables, while CFA focuses exclusively on the measurement model relating indicators to latent factors. If your goal is validating a scale, CFA is the right starting point.
What the lavaan Package Does in R
The lavaan package is a free, open-source R package for latent variable modeling, including confirmatory factor analysis, structural equation modeling, path analysis, and growth curve models. It was developed by Yves Rosseel at Ghent University and has become the dominant SEM tool in the R ecosystem.
Lavaan provides three main functions for fitting models. The cfa() function is a user-friendly wrapper designed specifically for fitting confirmatory factor analysis models. The sem() function is more general and handles full structural equation models with both measurement and structural components. The lavaan() function is the core function that underlies both, offering maximum flexibility with manual control over all options.
For most CFA workflows, the cfa() function is all you need. It automatically sets the scale of latent variables by fixing the first factor loading to 1, estimates model parameters using maximum likelihood by default, and provides convenient access to fit indices and parameter estimates. You can always switch to sem() or lavaan() when you need advanced features.
Lavaan uses a compact, readable syntax based on a few operators. The =~ operator defines a latent variable (the left side) measured by indicators (the right side). The ~~ operator specifies covariances or variances. The ~ operator specifies regression paths. This syntax is one reason lavaan became so popular. Once you understand three operators, you can specify complex models.
Step-by-Step: How to Conduct Confirmatory Factor Analysis in R with lavaan
The following tutorial walks through the complete CFA workflow in R using the lavaan package. Each step includes the exact code you need and an explanation of what the code does. You can copy and run these blocks in RStudio or any R environment.
Step 1: Install and Load the lavaan Package
If you have never used lavaan before, install it from CRAN first. Once installed, load it into your R session. This step takes less than two minutes.
install.packages("lavaan")
library(lavaan)
After loading the package, confirm it is working by checking the version. Running packageVersion("lavaan") should return the current version number. Keeping lavaan updated ensures you have the latest estimation methods and bug fixes.
Step 2: Load and Prepare Your Data
For this tutorial, I use the classic HolzingerSwineford1939 dataset, which ships with lavaan. It contains mental ability test scores from 301 students at two schools. The dataset includes nine test items that theoretically measure three latent factors: visual ability, textual ability, and speed ability.
data(HolzingerSwineford1939)
head(HolzingerSwineford1939)
str(HolzingerSwineford1939)
The nine indicators are named x1 through x9. According to the theoretical model, items x1, x2, and x3 load onto a visual factor. Items x4, x5, and x6 load onto a textual factor. Items x7, x8, and x9 load onto a speed factor.
Before fitting the model, check for missing values and verify that all indicator variables are numeric and continuous. Lavaan handles missing data with full information maximum likelihood (FIML) if you set the missing = "ml" argument, but it is still good practice to inspect your data first.
summary(HolzingerSwineford1939[, c("x1","x2","x3","x4","x5","x6","x7","x8","x9")])
Step 3: Specify the CFA Model Syntax
Model specification is where you translate your theoretical measurement model into lavaan syntax. This is the most important step because everything that follows depends on getting the syntax right.
Use the =~ operator to define each latent variable and its indicators. The left side of =~ is the latent variable name you choose, and the right side lists the observed indicators separated by plus signs.
cfa_model <- 'visual =~ x1 + x2 + x3
textual =~ x4 + x5 + x6
speed =~ x7 + x8 + x9'
By default, lavaan fixes the first loading of each factor to 1 for identification and freely estimates the remaining loadings. It also freely estimates the variances of the latent factors and the residual variances of the indicators. The correlations between latent factors are freely estimated by default.
If you want all factor loadings reported in the same metric, you can standardize later using the standardized = TRUE argument in summary(). For now, the default identification is standard practice and works for most applications.
Step 4: Fit the CFA Model with cfa()
Once the model is specified, fit it using the cfa() function. Pass the model syntax and the dataset as arguments.
fit <- cfa(cfa_model, data = HolzingerSwineford1939)
By default, lavaan uses maximum likelihood estimation. If your data deviates substantially from multivariate normality, consider using a robust estimator such as MLR by adding the estimator = "MLR" argument.
fit_robust <- cfa(cfa_model, data = HolzingerSwineford1939, estimator = "MLR")
MLR produces robust standard errors and a scaled chi-square test statistic that are more reliable under non-normality. Many published studies now default to MLR rather than standard ML for this reason.
Step 5: Summarize and View the Results
Call the summary() function on the fitted model object to see parameter estimates, standard errors, and test statistics. Add fit.measures = TRUE to include model fit indices and standardized = TRUE to include standardized estimates.
summary(fit, fit.measures = TRUE, standardized = TRUE)
The output has several sections. The top section reports the estimation method, the number of observations used, and the model chi-square test. Below that, you see parameter estimates grouped by factor loadings, covariances, and variances.
Each parameter estimate row includes an estimate, a standard error, a z-value, and a p-value. For factor loadings, the estimate tells you how strongly the indicator is associated with its latent factor. A standardized estimate above 0.5 is generally considered acceptable, and above 0.7 is considered good.
Step 6: Evaluate Model Fit Indices
Model fit indices tell you whether your hypothesized model adequately reproduces the observed covariance matrix. The summary output from the previous step includes these indices when fit.measures = TRUE is set.
The chi-square test compares your model to a saturated model. A non-significant chi-square (p > 0.05) indicates good fit, but this test is sensitive to sample size and almost always rejects the model in large samples. For this reason, researchers rely on approximate fit indices.
CFI (Comparative Fit Index) and TLI (Tucker-Lewis Index) values above 0.95 indicate excellent fit, and values above 0.90 indicate acceptable fit. RMSEA (Root Mean Square Error of Approximation) values below 0.06 indicate excellent fit, and below 0.08 indicate acceptable fit. SRMR (Standardized Root Mean Square Residual) values below 0.08 indicate acceptable fit.
You can also extract specific fit measures individually for cleaner reporting.
fitMeasures(fit, c("cfi", "tli", "rmsea", "srmr", "chisq", "df"))
Step 7: Examine the Standardized Solution
Standardized estimates are essential for interpreting and reporting CFA results because they are on a common scale and comparable across indicators. Extract them directly with the standardizedSolution() function.
standardizedSolution(fit)
This function returns a data frame with standardized parameter estimates, standard errors, z-values, and p-values for every estimated parameter in the model. Look at the rows where the left-hand side is a latent variable and the right-hand side is an indicator. The standardized estimate column shows the standardized factor loading.
Standardized loadings are what you report in papers and what reviewers expect to see. They range from roughly 0 to 1 in absolute value, with higher values indicating stronger relationships between indicators and their factors.
Step 8: Use Modification Indices for Model Improvement
If your model fit is below acceptable thresholds, modification indices can suggest changes that would improve fit. Each modification index estimates how much the model chi-square would decrease if a particular parameter were freely estimated.
modindices(fit, sort. = TRUE)
The output lists all fixed parameters in the model, sorted by modification index value in descending order. Parameters with high modification indices represent the biggest potential improvements to model fit.
Be cautious when using modification indices. Only add parameters that make theoretical sense, not just ones that improve fit numerically. Adding residual covariances between indicators within the same factor is often defensible if the items share method variance. Cross-loadings should only be freed if you have a strong substantive reason.
After adding a modification, refit the model and check whether fit indices improve meaningfully. Repeat this process sparingly. Every modification should be guided by theory and documented transparently in your research report.
How to Interpret CFA Output in lavaan
Interpreting CFA output comes down to three categories of parameters: factor loadings, residual variances, and latent factor covariances. Each tells you something different about your measurement model.
Factor loadings represent the strength of the relationship between each indicator and its latent factor. Unstandardized loadings are reported in the original metric of the data, while standardized loadings are on a correlation-like scale. For most reporting purposes, standardized loadings are more useful. A standardized loading of 0.7 or higher is considered good, 0.5 to 0.7 is acceptable, and below 0.5 suggests the indicator is weakly related to the factor.
Residual variances represent the portion of variance in each indicator not explained by its latent factor. High residual variances (above 0.5 in standardized terms) mean the factor explains less than half the variance in the indicator, which may prompt you to reconsider whether that item belongs in the scale.
Latent factor covariances tell you how strongly the factors are related to each other. Very high covariances (above 0.85 standardized) may indicate that two factors are measuring the same construct, raising concerns about discriminant validity. Very low covariances suggest the factors are largely independent.
Always check the p-values associated with each parameter. Significant p-values for factor loadings indicate that the relationship between indicator and factor is statistically reliable. Non-significant loadings suggest the indicator may not measure the intended construct well.
For real-world examples of how researchers interpret and report CFA output in published work, you can review published scale validation using CFA in academic journals, where the full workflow from model specification through interpretation is demonstrated with actual datasets.
Understanding Fit Indices: CFI, TLI, RMSEA, and SRMR
Fit indices are the primary way researchers evaluate whether a CFA model adequately fits the data. Each index measures fit from a slightly different angle, so reporting multiple indices is standard practice. Here is what each one means and what thresholds to apply.
The chi-square test statistic is the original and most fundamental fit measure. It tests the null hypothesis that the model-implied covariance matrix equals the observed covariance matrix. A significant chi-square (p < 0.05) suggests the model does not fit perfectly. However, chi-square is notoriously sensitive to sample size, and with large samples, even well-fitting models produce significant chi-square values. This is why researchers supplement it with approximate fit indices.
CFI (Comparative Fit Index) compares your model to a null or independence model that assumes zero covariances among variables. CFI ranges from 0 to 1, with values above 0.95 indicating excellent fit and values above 0.90 indicating acceptable fit. CFI is one of the most widely reported indices in published CFA studies.
TLI (Tucker-Lewis Index) is similar to CFI but penalizes for model complexity. It is sometimes called the Non-Normed Fit Index. TLI values above 0.95 indicate excellent fit. Because TLI penalizes complexity, it can sometimes be slightly lower than CFI for the same model.
RMSEA (Root Mean Square Error of Approximation) measures the discrepancy between the model-implied and observed covariance matrices per degree of freedom. RMSEA values below 0.06 indicate excellent fit, 0.06 to 0.08 indicates acceptable fit, and above 0.10 indicates poor fit. RMSEA also reports a 90 percent confidence interval, and a narrow interval below 0.08 strengthens your confidence in model fit.
SRMR (Standardized Root Mean Square Residual) is the average of the standardized residuals between the model-implied and observed covariance matrices. SRMR values below 0.08 indicate acceptable fit. SRMR is intuitive because it directly measures residual covariances in standardized units.
When reporting model fit, include at least the chi-square with degrees of freedom and p-value, CFI, TLI, RMSEA with confidence interval, and SRMR. Reviewers and methodologists expect to see all of these. If any index falls below the acceptable threshold, you should address it through model modification, indicator removal, or at minimum a transparent discussion of the limitation.
Common Problems and How to Fix Them
Even with a well-specified model, CFA in lavaan can produce surprising or problematic results. Here are the most common issues researchers encounter and how to address each one.
Negative variance estimates, also called Heywood cases, occur when lavaan estimates a negative residual variance for an indicator or a negative variance for a latent factor. This is mathematically impossible and signals a problem. Common causes include small sample sizes, indicators with very low reliability, or an over-fitted model. The fix is to either fix the negative variance to zero using the var1*0 syntax in your model or remove the problematic indicator entirely. If the problem persists, consider whether your factor structure is correctly specified.
Non-convergence happens when the estimation algorithm fails to reach a solution. Lavaan will print a warning message. Causes include poorly specified models, identification problems, starting values that are far from the optimum, or data with extreme multicollinearity. Try setting different starting values, simplifying the model, or checking for linear dependencies among indicators.
Poor model fit across all indices suggests the hypothesized structure does not match the data. Before abandoning the model, inspect the modification indices for clues about which parameters need adjusting. Common fixes include adding residual covariances between similarly worded items, removing indicators with low loadings, or reconsidering whether a different factor structure is more appropriate.
Confusion between cfa(), sem(), and lavaan() functions is a frequent question on forums. The cfa() function is optimized for pure measurement models and automatically handles factor scaling. The sem() function adds structural paths between latent variables. The lavaan() function gives you full manual control but requires you to set identification constraints yourself. For a standard CFA, always start with cfa().
Standardized versus unstandardized estimates confuse many users. Unstandardized estimates are in the original units of the data and are useful for comparing across groups or time points. Standardized estimates remove units of measurement and are useful for comparing the relative strength of relationships within a model. Report standardized loadings when discussing construct validity and indicator quality.
FAQ’s
How to conduct a confirmatory factor analysis in R?
To conduct CFA in R, install and load the lavaan package, load your dataset, specify the model using the =~ operator to define latent variables and their indicators, fit the model using the cfa() function, and evaluate results using summary(fit, fit.measures = TRUE, standardized = TRUE). Check fit indices like CFI, RMSEA, and SRMR against accepted thresholds.
What does lavaan do in R?
Lavaan is an R package for latent variable modeling that performs confirmatory factor analysis, structural equation modeling, path analysis, and growth curve modeling. It provides the cfa(), sem(), and lavaan() functions for fitting models using maximum likelihood estimation, along with tools for interpreting parameters, fit indices, and modification indices.
How to do confirmatory factor analysis?
Confirmatory factor analysis involves five stages: specify a theoretical factor structure based on prior research or theory, write model syntax defining which indicators load onto which latent factors, fit the model to data using estimation methods like maximum likelihood, evaluate model fit using indices such as CFI, TLI, RMSEA, and SRMR, and interpret factor loadings and residual variances to assess construct validity.
What is the EFA function in lavaan?
Lavaan does not have a dedicated EFA function. For exploratory factor analysis in R, use the factanal() function from base R or packages like psych and GPArotation. Lavaan is designed for confirmatory analysis where the factor structure is specified in advance. A common workflow is to run EFA using the psych package first, then confirm the discovered structure using lavaan’s cfa() function on a separate sample.
Conclusion
Learning how to conduct confirmatory factor analysis in R with lavaan opens the door to rigorous measurement model validation in any field that relies on latent constructs. The workflow comes down to eight clear steps: install lavaan, load and inspect your data, write the model syntax using the =~ operator, fit the model with cfa(), summarize the output with fit measures, evaluate fit indices against accepted thresholds, examine standardized loadings, and refine the model using modification indices when needed.
Remember that CFA is a confirmatory technique. The strength of the method lies in testing a theory you specified beforehand, not in letting the data drive your conclusions. When you modify a model based on modification indices, do so transparently and with theoretical justification. Report all fit indices and parameter estimates honestly, including standardized factor loadings and confidence intervals for RMSEA.
If your model fits well, you have established that your measurement instrument is valid and reliable for your sample. From there, you can proceed to structural equation modeling, multiple group comparisons, or longitudinal analysis with confidence that your latent variables are measuring what they should. The lavaan package handles all of these advanced techniques, and the syntax skills you learned in this tutorial transfer directly to those more complex models.