
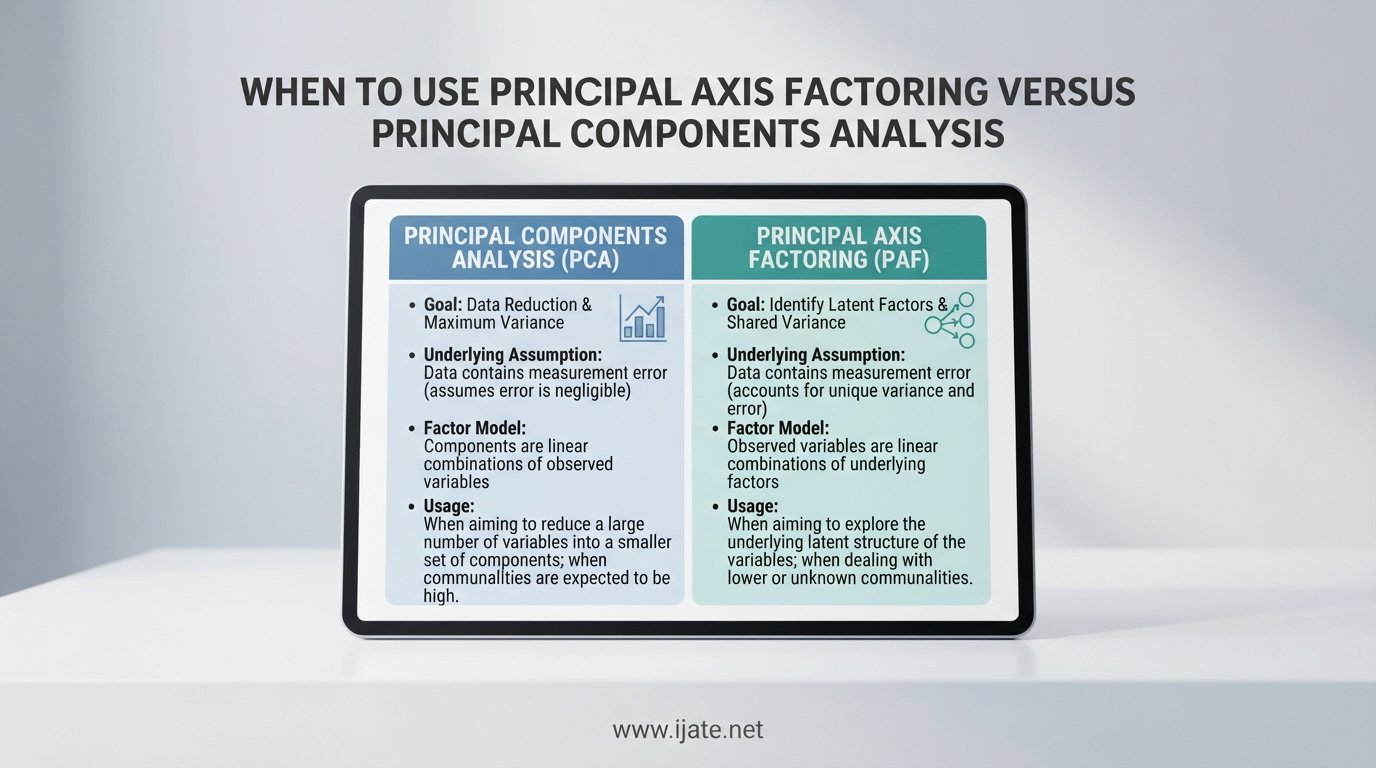
Principal axis factoring (PAF) and principal components analysis (PCA) are two of the most widely used multivariate techniques for reducing a large set of variables into a smaller set of components or factors. Despite their surface similarities, they answer fundamentally different research questions. PCA is a data reduction technique that creates linear combinations of your observed variables to summarize maximum variance. PAF is a factor extraction method that models underlying latent constructs by analyzing only the shared variance among variables. Choosing the wrong method can inflate your factor loadings, misrepresent your construct structure, and ultimately lead to misleading conclusions in your research.
The confusion between these two methods is widespread. On forums like Reddit’s r/AskStatistics and StackExchange, researchers routinely ask: “I know they are quite similar, but I am still having trouble differentiating between the two.” The short answer is that PCA analyzes the full correlation matrix with 1s on the diagonal, meaning it partitions total variance (common, unique, and error combined). PAF analyzes the reduced correlation matrix where communalities replace the 1s on the diagonal, meaning it partitions only common variance shared among variables. This single methodological difference cascades into different loadings, different eigenvalues, and different interpretations.
In this guide, we break down exactly when to use principal component analysis versus principal axis factoring, covering the mathematical foundations, the variance partitioning logic, the role of communalities, rotation methods, and a practical decision guide you can apply to your own datasets. Whether you are developing a psychometric scale, validating a survey instrument, or reducing dimensions for a machine learning pipeline, you will know which method fits your goal.
Table of Contents
What Is Principal Components Analysis (PCA)?
Principal components analysis is a dimensionality reduction technique that transforms a set of correlated variables into a smaller set of uncorrelated variables called principal components. Each principal component is a linear combination of all the original observed variables. The first component captures the maximum possible variance in the data, the second captures the maximum remaining variance under the constraint that it is uncorrelated with the first, and so on. PCA does not assume any underlying latent construct is generating the data. It simply re-expresses your data in a more compact form.
The key mechanical detail is that PCA operates on the full correlation matrix. This means the diagonal entries are all 1.0, representing the total variance of each variable. By using 1s on the diagonal, PCA treats all variance as fair game. It does not distinguish between variance that is shared with other variables (common variance), variance that is unique to a single variable (specific variance), and variance that is pure measurement error. Everything gets bundled together and redistributed across components.
This makes PCA powerful for data reduction but conceptually different from measuring latent constructs. If your goal is to compress 40 survey items into 5 composite scores for use in a regression model, PCA does this efficiently. The components themselves do not represent theoretical constructs. They represent mathematical summaries. Researchers and data scientists use PCA for image compression, feature engineering in machine learning, creating index variables, exploratory visualization of high-dimensional data, and any scenario where reducing dimensionality without losing too much information is the priority.
One important consequence of analyzing total variance is that PCA loadings tend to be higher than PAF loadings on the same dataset. This is because PCA capitalizes on all available variance, including the unique and error portions. Forum users on StackExchange frequently note this pattern: PCA gives higher loadings, which can mislead analysts into thinking they have well-defined factors when really the method is just absorbing noise into the components.
What Is Principal Axis Factoring (PAF)?
Principal axis factoring is a common factor analysis extraction method designed to identify underlying latent variables (factors) that explain the correlations among observed variables. Unlike PCA, PAF does not create linear combinations of your observed variables. Instead, it assumes that latent factors cause the observed correlations, and it works backward from the correlation matrix to estimate what those factors might look like.
The critical mechanical difference is that PAF operates on the reduced correlation matrix. In the reduced matrix, the 1s on the diagonal are replaced with communality estimates. These estimates represent the proportion of each variable’s variance that is shared with all other variables in the analysis. The most common initial communality estimate is the squared multiple correlation (SMC), which is the R-squared value obtained when regressing each variable on all other variables. By replacing 1s with communalities, PAF strips away unique and error variance before extracting factors.
This means PAF only analyzes common variance. The factors it extracts are estimates of latent constructs that produce the observed inter-correlations among variables. If you are developing a psychological scale to measure anxiety, for example, PAF helps you determine whether your 20 items actually reflect a smaller number of underlying anxiety dimensions. The factors have theoretical meaning. They are not just data summaries.
PAF is an iterative process in most implementations. After the initial extraction using SMC-based communalities, the procedure estimates new communalities from the extracted factors, replaces the diagonal again, and re-extracts. This continues until the communality estimates stabilize. The final solution represents the best estimate of the common factor structure underlying your data. Researchers in psychology, education, social sciences, and market research rely on PAF when they need to identify or confirm the dimensional structure of a set of indicators.
Variance Partitioning: The Core Methodological Difference
Understanding variance partitioning is the single most important step in grasping why PCA and PAF produce different results. Every variable in your dataset has a total variance that can be decomposed into three parts: common variance, unique variance, and error variance. Common variance is the portion of a variable’s variance that is shared with other variables through underlying factors. Unique variance is specific to that variable and not shared with anything else. Error variance is random measurement noise.
PCA uses total variance. Because the diagonal of the correlation matrix contains 1s, PCA distributes all three types of variance across components. This is mathematically equivalent to saying that PCA treats each variable as if it has perfect reliability, with a communality of 1.0. The components that emerge are mixtures of shared signal and variable-specific noise. For pure data reduction, this is perfectly fine. You want to capture as much information as possible in as few components as possible.
PAF uses only common variance. By replacing the diagonal 1s with communality estimates (typically SMCs), PAF removes unique and error variance from the analysis before extracting factors. The factors that emerge represent only the shared structure among variables. This is the appropriate approach when your goal is to model latent constructs, because you do not want idiosyncratic item variance or measurement error to contaminate your factor structure.
Here is a concrete illustration. Suppose you have 10 items measuring customer satisfaction, and item 3 happens to be poorly worded, introducing substantial unique variance. PCA would absorb that unique variance into the components, potentially creating a component that looks important but is really driven by one badly written item. PAF would down-weight item 3 because its low communality signals that it does not share much variance with the other items. The resulting factor structure would be cleaner and more theoretically meaningful.
This difference in variance partitioning also explains why eigenvalues from PCA are always larger than eigenvalues from PAF on the same data. PCA eigenvalues reflect total variance explained, while PAF eigenvalues reflect only common variance explained. When researchers compare scree plots across the two methods, the PCA curve sits consistently above the PAF curve. This does not mean PCA found more factors. It means PCA is counting more variance.
The distinction matters most when communalities are low. If your variables have high communalities (above 0.80), the difference between PCA and PAF shrinks dramatically because there is little unique or error variance to partition differently. But when communalities are moderate (0.30 to 0.60), the methods diverge significantly, and choosing the correct one becomes critical. As forum users have observed, with 40 or more variables and high communalities, PCA and PAF produce nearly identical results. With fewer variables and moderate communalities, the gap is substantial.
Full Correlation Matrix vs Reduced Correlation Matrix
The distinction between the full correlation matrix and the reduced correlation matrix is where theory meets computation. The full correlation matrix is what you see when you run a standard correlation analysis. Every off-diagonal entry is the Pearson correlation between two variables, and every diagonal entry is 1.0, representing the perfect correlation of each variable with itself. PCA uses this full matrix directly.
The reduced correlation matrix is the same matrix except the 1s on the diagonal are replaced with communality estimates. These estimates tell the analysis how much of each variable’s variance is shared with the rest of the variable set. The reduced matrix is sometimes called the reproduced or adjusted correlation matrix because it reflects only the shared-structure portion of the relationships among variables.
Why does replacing the diagonal matter so much? In eigendecomposition, the diagonal values weight how much each variable contributes to each extracted component or factor. When the diagonal contains 1s, every variable contributes its full variance. When the diagonal contains communalities below 1, variables with low shared variance contribute less to the factor solution. This is exactly what you want when measuring latent constructs. Variables that do not correlate well with others should not dominate the factor structure.
Squared multiple correlations serve as the starting communalities because they provide a conservative, data-driven estimate of how much each variable overlaps with all others combined. The SMC for variable X is obtained by regressing X on all other variables in the analysis and taking the resulting R-squared. An SMC of 0.65 means that 65% of X’s variance can be predicted from the other variables, which serves as a reasonable lower-bound estimate of X’s communality.
One common point of confusion is that communalities change during the PAF extraction process. The initial communalities (SMCs) are starting values. After the first extraction, PAF computes new communalality estimates from the extracted factor loadings, inserts those into the diagonal, and re-extracts. This iteration continues until the communalities converge. The final communalities reported in your output reflect the shared variance explained by the retained factors, not the initial SMC estimates.
PCA vs PAF: Side-by-Side Comparison
The following comparison summarizes the key differences between principal components analysis and principal axis factoring across multiple dimensions. Use this as a quick reference when deciding which method fits your research goal.
- Primary Goal: PCA aims for data reduction and dimensionality reduction. PAF aims for latent construct identification and measurement model specification.
- Correlation Matrix: PCA analyzes the full correlation matrix with 1s on the diagonal. PAF analyzes the reduced correlation matrix with communalities on the diagonal.
- Variance Analyzed: PCA partitions total variance (common plus unique plus error). PAF partitions only common variance.
- Direction of Causality: In PCA, components are linear combinations of observed variables (variables cause components). In PAF, latent factors cause the observed correlations (factors cause variable scores).
- Initial Communalities: PCA assumes communalities of 1.0 for all variables. PAF uses squared multiple correlations as initial communality estimates.
- Typical Eigenvalues: PCA eigenvalues are larger because they include total variance. PAF eigenvalues are smaller because they include only common variance.
- Typical Loadings: PCA loadings tend to be higher. PAF loadings tend to be lower but more theoretically clean.
- Best Suited For: PCA suits data scientists, engineers, and researchers doing prediction or visualization. PAF suits social scientists, psychologists, and researchers developing scales or validating instruments.
- Assumption About Error: PCA does not separate measurement error from true score variance. PAF explicitly separates error variance from common variance.
- Statistical Model: PCA is a transformation technique with no underlying statistical model. PAF is grounded in the common factor model with explicit assumptions about latent variables.
When to Use PCA vs PAF: A Decision Guide
Choosing between PCA and PAF comes down to one fundamental question: are you trying to reduce data or measure a latent construct? If your goal is data reduction, PCA is the right tool. If your goal is understanding the structure of unobserved variables that explain why your observed variables correlate, PAF is the right tool. The decision flows from your research objective, not from which method gives you better looking numbers.
Use PCA when your primary objective is one of the following: compressing a large number of variables into a smaller number of composite scores for downstream analysis, creating an index or summary variable from multiple indicators, preprocessing data for machine learning algorithms that struggle with multicollinearity, visualizing high-dimensional data in two or three dimensions, or removing redundant variables from a dataset. In all of these cases, you do not need the components to represent theoretically meaningful constructs. You just need them to capture as much information as possible in as few dimensions as possible.
Use PAF when your primary objective is one of the following: developing a new psychometric scale or measurement instrument, validating the factor structure of an existing scale, identifying the dimensionality of a set of indicators that are hypothesized to reflect underlying constructs, testing whether items group together in theoretically expected ways, or preparing for confirmatory factor analysis where you need to specify a measurement model. In all of these cases, you want the factors to represent real latent variables, and you want to exclude measurement error and item-specific variance from the solution.
Consider this practical scenario. A researcher has collected responses on a 30-item personality questionnaire and wants to identify the underlying personality traits. PAF is appropriate here because personality traits are latent constructs that cannot be directly observed. The items are indicators of those constructs, and the researcher needs to know how many traits the items reflect and which items load on which traits. Using PCA would be methodologically inappropriate because components are not latent constructs. They are mathematical summaries that confound shared variance with item-specific noise.
Now consider a different scenario. A data scientist has 200 features from customer transaction data and needs to reduce dimensionality before feeding the data into a neural network. PCA is the right choice because the goal is purely computational efficiency. The principal components do not need to represent meaningful business constructs. They just need to preserve as much predictive information as possible while reducing the feature space from 200 to perhaps 30 or 50.
A third scenario sits in a gray zone. A marketing researcher has 15 brand perception ratings and wants to understand the key dimensions along which consumers differentiate brands. This could go either way. If the researcher wants to identify underlying perceptual dimensions (like quality, value, and trustworthiness), PAF is more appropriate because those dimensions are latent constructs. If the researcher just wants a few composite scores to use as independent variables in a choice model, PCA is acceptable and simpler.
The sample size and communality levels also influence the decision. When communalities are high (above 0.70) and the sample is large, PCA and PAF converge on similar solutions, making the choice less critical. When communalities are moderate or low, the methods diverge, and choosing correctly becomes more important. Run both methods on your data and compare the results. If they produce substantially different factor structures, you need to think carefully about which one aligns with your research question.
Finally, consider the role of theory. If you have a strong theoretical model predicting that certain variables should group together because they reflect a common latent cause, PAF is the method that actually tests that model. PCA does not test any causal theory. It just reorganizes variance. This is why methodologists consistently recommend PAF (or maximum likelihood factor analysis) over PCA for scale development and construct validation work.
Common Misconceptions About PCA and PAF
Several persistent myths about PCA and PAF circulate in graduate seminars, online forums, and even published research. Addressing these misconceptions directly helps researchers avoid methodological errors that can undermine their findings.
Misconception 1: PAF is just PCA with a different name. This is false. While both methods use eigendecomposition as their computational engine, they operate on different matrices (full versus reduced), analyze different types of variance (total versus common), and serve different theoretical purposes (data reduction versus latent construct measurement). Conflating the two leads to inappropriate applications, such as using PCA when a measurement model is needed.
Misconception 2: PCA is a type of factor analysis. PCA is not factor analysis in the strict sense. Factor analysis refers to a family of methods that model latent common factors as the cause of observed correlations. PCA creates components as consequences of observed variables. The causal direction is reversed. Some software packages list PCA under factor analysis menus, which contributes to this confusion, but methodologically they are distinct techniques with different statistical models.
Misconception 3: Higher loadings from PCA mean better factors. PCA consistently produces higher loadings than PAF on the same data because it capitalizes on total variance rather than just common variance. These inflated loadings do not indicate a superior factor solution. They indicate that PCA is absorbing unique and error variance into the components. For construct measurement purposes, the lower but cleaner loadings from PAF are more trustworthy because they reflect only shared variance among items.
Misconception 4: It does not matter which method you use with large datasets. It is true that PCA and PAF converge when communalities are high and there are many variables. But many real-world datasets have moderate communalities, and even with 40 or more variables, the factor structures can differ in meaningful ways. Always check communalities and compare solutions rather than assuming the choice is irrelevant.
Misconception 5: You should always default to PCA because it is simpler. Simplicity is not a valid reason to choose a method that answers the wrong question. If your research question involves latent constructs, using PCA because it is easier to run or interpret is a methodological error. The correct approach is to use the method that matches your research objective, even if it requires more careful interpretation.
Rotation Methods: Varimax, Oblique, and Promax
Both PCA and PAF produce initial solutions that are often difficult to interpret because the factors or components are extracted to maximize variance or fit mathematical criteria, not to produce interpretable structure. Rotation addresses this by redistributing the variance among factors to achieve what Thurstone called simple structure: each variable loads highly on one factor and near zero on all others. The choice of rotation applies to both PCA and PAF, though it is more commonly discussed in the context of factor analysis.
Varimax is the most popular orthogonal rotation method. It maintains the 90-degree angle between factors, meaning the rotated factors remain uncorrelated. Varimax simplifies interpretation by maximizing the variance of squared loadings within each factor. This tends to produce solutions where each variable loads strongly on exactly one factor, making it easy to assign variables to factors. However, the assumption that latent constructs are perfectly uncorrelated is often unrealistic in social science research. Anxiety and depression, for example, are known to correlate substantially.
Oblique rotation methods, including Direct Oblimin and Promax, allow factors to correlate. This is more realistic for most psychological and social science constructs. Direct Oblimin uses a parameter called delta that controls the degree of correlation allowed among factors. Promax achieves oblique rotation by first performing Varimax and then raising the loadings to a power to sharpen the simple structure. Both methods produce a pattern matrix (the factor loadings in the rotated solution) and a structure matrix (the correlations between variables and factors, which include the indirect effects through factor correlations).
The choice between orthogonal and oblique rotation should be guided by theory. If your theoretical model treats the constructs as independent, orthogonal rotation like Varimax is defensible. If theory suggests the constructs should correlate, oblique rotation is more appropriate. Many methodologists recommend defaulting to oblique rotation because if the factors are truly uncorrelated, oblique rotation will simply estimate near-zero correlations and produce a solution very similar to the orthogonal one. If they are correlated, forcing orthogonality distorts the loadings.
It is worth noting that rotation does not change the total variance explained by the factor solution. It redistributes variance among the retained factors for easier interpretation. A three-factor PAF solution explains the same amount of common variance before and after Varimax rotation. What changes is how that variance is allocated across the three factors, which directly affects how you interpret and label them.
PAF vs Maximum Likelihood: A Third Option
Principal axis factoring is not the only method for extracting common factors. Maximum likelihood (ML) factor analysis is a popular alternative that offers several advantages. Like PAF, ML analyzes the reduced correlation matrix and models latent constructs. Unlike PAF, ML provides a formal statistical test of model fit through a chi-square statistic, produces standard errors and confidence intervals for factor loadings, and allows computation of fit indices such as the Comparative Fit Index (CFI) and Root Mean Square Error of Approximation (RMSEA).
These additional outputs make ML attractive when you need to compare competing factor models or report formal fit statistics in a publication. ML also assumes multivariate normality of the observed variables, which can be a limitation with ordinal data or heavily skewed distributions. PAF makes no distributional assumptions, which makes it more robust for non-normal data.
When should you choose ML over PAF? If you plan to move toward confirmatory factor analysis, ML is the better choice because it shares the same estimation framework. If you need to compare the fit of a two-factor model against a three-factor model using statistical criteria, ML provides the tools to do so. If your data are ordinal or non-normal, or if you want a simple, robust extraction method without distributional assumptions, PAF remains a solid choice.
In practice, many researchers run both PAF and ML on the same data and compare the solutions. If both methods produce similar factor structures, you can be more confident in your results. If they diverge, you need to investigate which solution better fits the data using fit indices, theory, and practical interpretability.
How to Implement PCA and PAF in SPSS
SPSS is the most commonly used software for both PCA and PAF, particularly in social science research. The procedure for running both methods is nearly identical, which contributes to the confusion between them. Understanding the specific settings helps ensure you are running the correct analysis for your research question.
To run PCA in SPSS, navigate to Analyze, then Dimension Reduction, then Factor. Move your variables into the analysis box. In the Extraction dialog, the default method is PCA. SPSS lists PCA as the first option in the Method dropdown, which makes it easy to accidentally run PCA when you intended to run PAF. For PCA, the extraction operates on the full correlation matrix with communalities fixed at 1.0.
To run PAF, select Principal Axis Factoring from the Method dropdown. This changes the analysis to use the reduced correlation matrix with SMC-based communalities on the diagonal. You can also specify the number of factors to extract, choose a rotation method, and request scree plots and factor loading displays. The output for PAF will show initial communalities (SMCs), extraction communalities (final estimates), eigenvalues for the reduced matrix, and rotated factor loadings.
A common point of confusion in SPSS output is that PCA results are displayed within the Factor Analysis procedure, with tables labeled communalities, eigenvalues, and factor loadings. This labeling makes PCA look like factor analysis. But examining the communalities table reveals that PCA sets initial communalities to 1.0 for every variable, which is the telltale sign that the full correlation matrix is being analyzed. In PAF, the initial communalities will be values less than 1.0, reflecting the SMC estimates.
Frequently Asked Questions
Are PCA and EFA the same?
No, PCA and EFA are not the same. Principal Components Analysis (PCA) is a data reduction technique that creates linear combinations of observed variables using the full correlation matrix. Exploratory Factor Analysis (EFA), which includes methods like PAF and maximum likelihood, is a latent variable modeling technique that uses the reduced correlation matrix to identify underlying constructs. PCA analyzes total variance while EFA analyzes only common variance.
What is the difference between PCA and CFA?
PCA is an exploratory data reduction technique with no underlying causal model. Confirmatory Factor Analysis (CFA) is a hypothesis-testing method that specifies a predetermined factor structure and tests how well the data fit that structure. PCA creates components from variables, while CFA tests whether a theoretical factor model reproduces the observed correlations. CFA uses maximum likelihood estimation and provides formal fit statistics.
What is the difference between PCA and PLS analysis?
PCA is an unsupervised dimensionality reduction technique that does not use an outcome variable. Partial Least Squares (PLS) is a supervised method that creates components specifically to maximize prediction of a dependent variable. PCA finds components that capture maximum variance in the predictors alone, while PLS finds latent variables that maximize covariance between predictors and outcomes.
What is the difference between PCA and CCA analysis?
PCA reduces a single set of variables into principal components that capture maximum variance. Canonical Correlation Analysis (CCA) examines the relationships between two sets of variables by finding linear combinations from each set that are maximally correlated with each other. PCA works within one variable set, while CCA works across two variable sets simultaneously.
Why does PAF use a reduced correlation matrix?
PAF uses the reduced correlation matrix because its goal is to model only the common variance shared among variables. By replacing the 1s on the diagonal with communality estimates (typically squared multiple correlations), PAF removes unique and error variance from the analysis. This ensures the extracted factors represent latent constructs rather than mathematical summaries that confound shared variance with item-specific noise.
Should I use PCA or PAF for scale development?
You should use PAF (or maximum likelihood factor analysis) for scale development. Scale development requires identifying latent constructs, which is the purpose of common factor analysis methods like PAF. PCA is inappropriate for scale development because it analyzes total variance rather than common variance, produces inflated loadings, and does not model latent constructs. Methodologists consistently recommend PAF or ML for instrument validation work.
Conclusion
Understanding when to use principal axis factoring versus principal components analysis comes down to knowing what question you are asking of your data. PCA answers the question: how can I compress these variables into fewer components while retaining maximum information? PAF answers the question: what latent constructs explain the pattern of correlations among these variables? These are fundamentally different questions, and using the wrong method produces results that are mathematically valid but substantively misleading.
The key takeaways are straightforward. PCA analyzes total variance through the full correlation matrix with 1s on the diagonal. PAF analyzes common variance through the reduced correlation matrix with communalities on the diagonal. PCA produces components that are linear combinations of observed variables. PAF produces factors that are latent causes of observed correlations. PCA loadings are typically higher because they capitalize on all variance. PAF loadings are lower but more theoretically clean because they reflect only shared structure.
For scale development, construct validation, and any research involving latent variables, PAF (or maximum likelihood factor analysis) is the methodologically correct choice. For data compression, feature engineering, visualization, and any application where components serve as mathematical summaries, PCA is appropriate and efficient. When communalities are high and variable counts are large, the two methods converge, but you should always verify this rather than assuming it.
The best practice is to think carefully about your research objective before opening your statistical software. Let theory guide your choice of method, not the other way around. Run both methods if you are unsure, compare the solutions, and choose the one that aligns with the question your research is actually trying to answer. By understanding the distinction between principal axis factoring and principal components analysis, you ensure that your factor analytic work is both statistically sound and substantively meaningful.